Application Performance Monitoring: How APM Works
- APM tool
- Change history
- Loglune
Application performance monitoring (APM) is the practice of collecting telemetry from running software, such as response time, throughput, error rate, and traces, so a team can find and fix performance problems before users are affected. An APM tool instruments the application, sends the data to a central platform, and alerts when a metric crosses a threshold. This guide explains what APM measures, how it works, how it differs from observability and from application performance management, how to choose APM software, and how to connect a regression to the change that caused it.
The guide covers APM for web and backend software run by a development or operations team. It closes a gap that most APM explainers leave open: an APM tool shows that one group of customers got slower, but it does not record which feature flag or configuration change reached that group. After reading, the team can pick the metrics to alert on, compare APM tools on the same criteria, and trace a segment-level regression to the flag change behind it. Network monitoring and infrastructure-only monitoring use some of the same metrics and are outside the scope.
What application performance monitoring means
Application performance monitoring means measuring how a running application behaves for its users and alerting the team when that behavior gets worse. In other words, APM is the process of using software tools and telemetry data to monitor the performance of business-critical applications.
The reason teams adopt APM is that code review and tests describe the software before release, while APM describes it after release, under real traffic. Latency and throughput are examples of the key performance indicators an APM tool tracks over time to surface trends and outliers.
For example, an APM tool can show that checkout requests took twice as long after 14:00 and that the slow requests all passed through one database call. The team then knows where to look before customers file tickets.
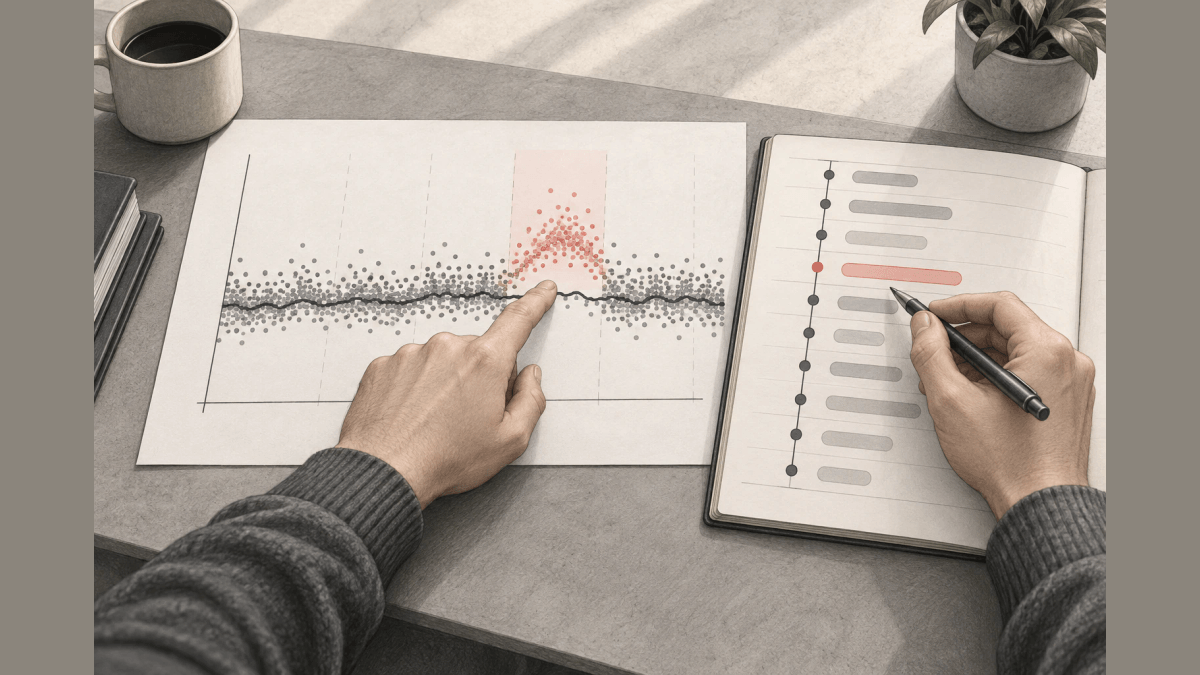
APM shows that something changed and where in the request path the time went. APM data by itself does not record which configuration or flag change caused the shift, which is why the regression section later in this guide pairs APM with a change history.
What APM measures
APM measures how fast the application responds, how much work it handles, how often it fails, and where the time goes inside each request. The table lists the common metrics.
| Metric | What it tells you |
|---|---|
| Response time (latency) | How long the application takes to answer a request |
| Throughput | Requests or transactions handled per period, often requests per minute (RPM) |
| Error rate | Share of requests that fail, such as timeouts or failed database queries |
| Transaction tracing | The function, external, and database calls inside a single request, from start to finish |
| CPU and memory usage | Whether the application gets the compute resources it needs |
| Instances | How many server or application instances are running |
| Uptime | Availability compared with the level in the service level agreement |
Teams track several metrics because each one misses a kind of failure. A fast endpoint with a rising error rate is still broken, and a reliable endpoint with high latency still frustrates users. For example, APM can fire an alert when 5% of the last 50 requests have resulted in an error.
Apdex: one score for response time
Apdex turns response time samples into one score between 0 and 1. The Apdex technical specification by Peter Sevcik of NetForecast sets a target time T. A response at or under T counts as satisfied, a response between T and F counts as tolerating, and a response slower than F counts as frustrated, where F is four times T. The score is the satisfied count plus half the tolerating count, divided by the total number of samples.
Editorial example (not customer data): with T set to 0.5 seconds, F is 2 seconds. Out of 1,000 requests, 800 finish within 0.5 seconds, 100 finish between 0.5 and 2 seconds, and 100 take longer than 2 seconds. The score is (800 + 100 / 2) / 1,000 = 0.85. The specification gives the same 0.85 result for 80% satisfied, 10% tolerating, and 10% frustrated.
Apdex hides which users were frustrated. A score of 0.85 can mean every user had a few slow requests, or one customer segment had nothing but slow requests, so read Apdex next to latency split by customer or segment.
Real user monitoring vs synthetic monitoring
Real user monitoring (RUM) measures the requests your actual users make, and synthetic monitoring sends scripted requests on a schedule to test paths before users hit them. RUM captures actual user interactions, and synthetic monitoring simulates user activity to detect issues before they occur.
The two answer different questions. RUM tells you what users experienced, including slow page loads and frontend errors from their browsers or devices. Synthetic checks tell you whether a path works at 3 a.m. when no real user is on it, or before a release reaches production.
| Real user monitoring | Synthetic monitoring | |
|---|---|---|
| Traffic | Requests from real users | Scripted requests on a schedule |
| Finds | Problems users already hit, by device, region, or segment | Broken or slow paths before users hit them |
| Blind spot | Paths nobody used in the period | Behavior that depends on real user data or settings |
Synthetic monitoring cannot reproduce a problem that depends on who the user is. If a slowdown hits enterprise accounts because a setting applies to them alone, a synthetic script logged in as a test account on the free plan passes while enterprise customers wait.
How APM works
APM works in three steps: instrument the application, send the telemetry to a central platform, and correlate the data into alerts and views. The same three steps are often named data collection and instrumentation, data transmission and aggregation, and data processing and correlation.
- Instrument the application. An agent or SDK inside the application records request timings, errors, and trace spans. An agent is software placed in the application that sends trace and telemetry data to the APM server, and APM explainer notes native support for OpenTelemetry, the open standard for this data.
- Send and aggregate the telemetry. The agents send data from every instance to one platform, which stores it with the service, host, and version it came from.
- Correlate and alert. The platform links metrics, traces, and logs for the same request. For example, the platform can link one user’s slow page load to the trace that shows which backend service was slow, and then to that service’s log entries.
The reason for this pipeline is that a single request crosses many services, and no one service can see the full path. Instrumentation has a cost: agents add overhead, and Elastic notes that complex, distributed applications can make APM instrumentation a challenge.
APM vs observability and APM vs application performance management
APM is a part of observability, and application performance monitoring is a part of application performance management. AWS states that “APM is a subset of observability,” and IBM’s APM page describes monitoring tools as one aspect of application performance management.
| Term | Scope | Typical question |
|---|---|---|
| Application performance monitoring | Metrics and traces for one application’s performance | Is checkout slower than yesterday? |
| Application performance management | Monitoring plus the work of tuning and fixing based on it | What do we change so checkout stays fast? |
| Observability | Logs, metrics, and traces across the whole stack, correlated | Why did this request behave this way, even if we never predicted the question? |
The distinction matters when comparing tools. Management goes a step further than monitoring by optimizing based on what monitoring finds. Observability brings data from the entire IT stack into one platform and using tools such as distributed tracing beyond the aggregate metrics of APM. IBM adds that the classic APM approach is ill-equipped for distributed applications that run across many runtimes, which is where observability platforms took over.
In everyday use the lines blur. The same APM abbreviation is used for both, and many vendors sell APM as one module of an observability platform.
Benefits of application performance monitoring
APM shortens the time from a performance problem to its fix, and it shows the impact of each change on users. AWS lists customer satisfaction, rapid diagnosis, reduced operating costs, effective product development, and business collaboration as benefits.
- Faster detection. Alerts on latency and error rate fire before support tickets arrive.
- Faster diagnosis. Traces point to the slow service or query, so the team skips guessing.
- Release feedback. Comparing metrics before and after a deploy shows whether the release helped or hurt.
- Capacity planning. Resource and instance metrics show how much infrastructure the application needs.
- Shared facts. Product, support, and engineering read the same numbers during an incident.
The goal is to notice when the app gets slower, find out why, alert when error rates rise, and roll back broken changes.
The limit is that the benefits depend on instrumentation coverage. A service without an agent, or a change that APM does not record, leaves a gap in the picture.
How to choose APM software
Choose APM software by checking that it supports your languages and runtimes, fits your existing tools, and has a cost you can sustain as traffic grows. The criteria below combine the lists in the AWS and Elastic explainers.
- Language and framework support. AWS says the platform must support your programming language. Check every service, including the small ones.
- Open standards. Elastic lists open standards among its criteria. Instrumenting with OpenTelemetry keeps the data portable if you change vendors.
- Integrations. Elastic lists integrations among its criteria. The tool should read from and alert into what the team already uses, such as logs, chat, and the incident management process.
- Deployment and ease of use. Elastic lists both. Check whether the tool runs as a hosted service or on your own infrastructure, and how much setup each service needs.
- Cost. AWS notes that APM can demand considerable compute resources. Model the cost at your request volume and data retention.
- Ownership and buy-in. AWS asks who will own and maintain the APM, and whether teams understand why it is being introduced.
- Change correlation. Datadog’s APM product page describes correlating “application performance issues with code deployments, feature flags, configuration changes, and DB modifications.” Check which change sources your tool can show next to a regression.
No single criterion picks the tool. A team with five services in two languages weighs language support first, while a team with high request volume weighs cost and sampling controls first.
How to connect an APM regression to a flag change
To connect an APM regression to a flag change, take the affected segment and the start time from APM, list the flag changes around that time, and then find the first change that flipped the flag evaluation for an affected customer at that time. A performance regression raises three questions: which requests got slower, for which customers, and since when; which flag changes happened in that window; and which change flipped the evaluation for the affected customer at time T. The steps below assume your feature flags run on a platform that keeps a change history.
- Read the regression from APM. Note when the latency or error rate rose, and which customers, plans, or regions it affects. The start time becomes time T.
- List the flag changes around T. Pull every flag change event with its actor, time, and values before and after, then keep the ones near the start of the regression.
- Pick an affected customer and their attributes. Use the customer identifier and the attributes your flag rules read, such as plan, for one customer in the affected segment.
- Search the history for the change that flipped the evaluation. A binary search over the change history, the same idea as git bisect over commits, evaluates the flag for that customer at each step and stops at the first change that turned the value to the bad one.
- Check an unaffected customer. Run the same search for a customer outside the segment. If nothing flips, the change explains why one segment regressed and the other did not.
The reason to search instead of reading the list is that several flags often change in the same hour, and the change closest in time is not always the one that reached the affected customer. The limit is that a flag change explains a regression only when the flag gates the slow code path. If no flag evaluation flipped, the cause sits in a deploy, a dependency, or the infrastructure, and the APM traces stay the place to look.
In Loglune, every flag edit is stored as a change event, and the flag state at time T is rebuilt from the events up to T. The audit view lists the change events with the actor, the time, the values before and after, and the version that first published each one. The bisect view binary-searches the change history for the first change that flipped the evaluation, and when the change cannot be confirmed it ends as unconfirmed instead of naming a guess. If an attribute the rules read is missing, bisect returns the missing attribute name instead of filling it in. Loglune reproduces flag evaluation and does not determine the cause of an application failure, so the APM data and the flag result are read together. The walkthrough on reproducing a bug that affects one customer covers the next step after the change is found.
Editorial example (not a customer case): tracing an enterprise latency regression to a flag change
We ran the shipped control route on a local test database on October 6, 2026, with editorial example flags. No APM data was collected; the regression described below is the scenario the run was built around. Suppose an APM tool shows search latency rising for enterprise accounts from about 13:40 UTC, while free accounts stay flat.
The run created three flags with default off at 09:00 UTC (search-v2, promo-banner, pdf-export-async) and published version 1. It then made three changes, each followed by a publish.
| seq | Time (UTC) | Flag | Change | First published in |
|---|---|---|---|---|
| 4 | 13:40:00 | search-v2 |
Rules [] to [enterprise-on] (plan in enterprise returns on) |
Version 2 |
| 5 | 14:05:00 | promo-banner |
Default off to on |
Version 3 |
| 6 | 14:20:00 | pdf-export-async |
Rules [] to [free-on] (plan in free returns on) |
Version 4 |
The audit returned all six events with the actor dev@example.com, and the audit chain check returned "verified": true with "count": 6. The publish check flagged one change: for version 3 it returned a defaultFlip finding for promo-banner from off to on with severity high. The rule added to search-v2 produced no publish finding, so a list of warnings alone would have pointed at the wrong flag.
Bisect then searched the history for the first change that turned each flag to true at T = 14:30 UTC.
| Flag | Customer attributes | T (UTC) | Verdict | Result |
|---|---|---|---|---|
search-v2 |
plan enterprise | 14:30 | confirmed |
seq 4 at 13:40:00, version 2, from off (reason default) to on (reason targetMatch, rule 0) |
search-v2 |
plan free | 14:30 | none |
Inspected seq 3 to 6, no flip |
search-v2 |
plan enterprise | 13:30 | none |
Inspected seq 3 to 3, no flip |
pdf-export-async |
plan enterprise | 14:30 | none |
No flip for an enterprise account |
search-v2 |
none sent | 14:30 | insufficient-input |
Missing ["plan"] |
The confirmed result names the search-v2 rule added at 13:40 as the change that flipped the evaluation for an enterprise account, which matches the start time and the segment in the APM scenario. The promo-banner default flip at 14:05 happened later, and the pdf-export-async rule reached free accounts alone. Without the plan attribute, bisect did not guess the plan and asked for it.
The example shows which flag change reached the segment, and stops there. Whether the new search path is the slow code still has to be confirmed in the APM traces for those requests.
Limits of application performance monitoring
APM measures symptoms in the running application and does not, by itself, explain every cause. Honeycomb’s APM article lists limitations of APM, and IBM’s page notes the gap with distributed applications across multiple runtimes.
- Aggregates hide segments. Averages and Apdex can stay flat while one customer group regresses.
- Coverage gaps. Uninstrumented services, third-party calls, and batch jobs can be missing from traces.
- Change blindness. A setting or flag change does not appear in request metrics unless the tool ingests change events.
- Data volume and cost. Full tracing at high traffic needs sampling, and sampled traces can miss rare slow requests.
Where to start with application performance monitoring
Start application performance monitoring by instrumenting the services on your most important user path, alerting on latency and error rate, and adding real user monitoring for the frontend. Split latency by customer segment so a regression in one group is not averaged away. When a regression hits one segment and lines up with a configuration or flag change, list the changes in that window and search for the first one that flipped the evaluation for an affected customer, then confirm the slow path in the APM traces.
Find the flag change behind an application performance monitoring regression
When application performance monitoring shows that some customers got slower or started seeing errors, part of the investigation is working out which change reached them. Loglune records every flag edit as a change event with the actor, the time, and the values before and after, and binary-searches that history for the first change that flipped a customer's flag evaluation at time T. Loglune does not collect application metrics, so it works next to your APM tool. The Free plan includes 5 reproductions.