MTTR: How to Measure and Reduce It in 7 Steps
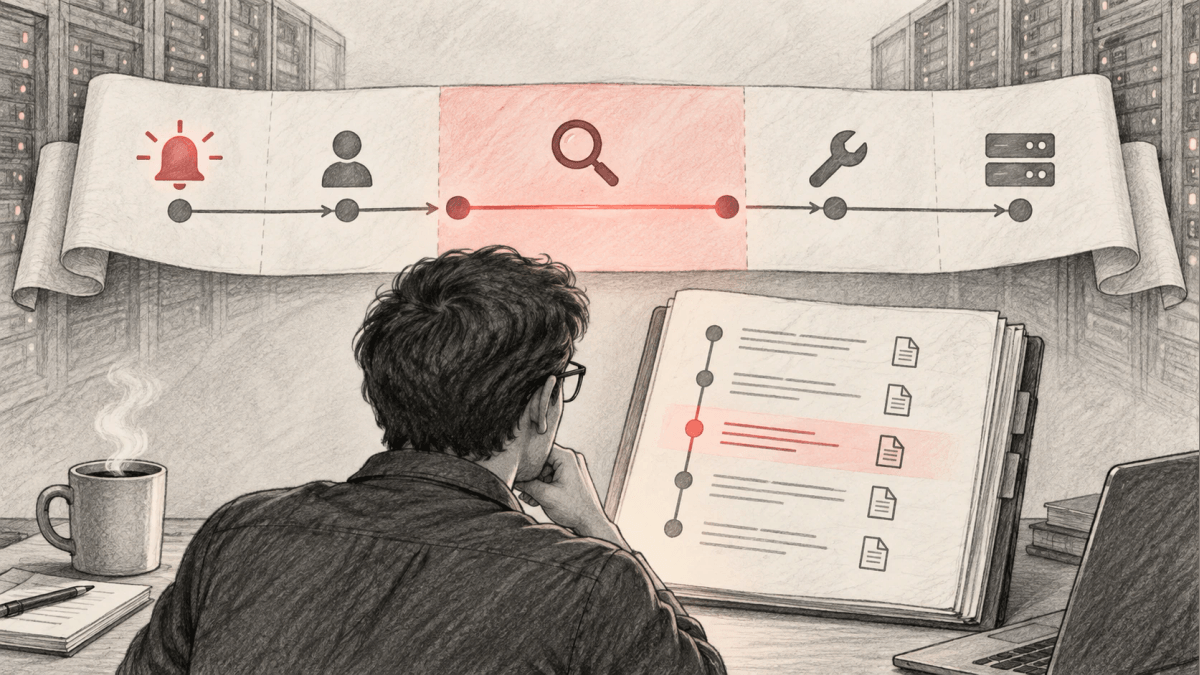
- Detect and acknowledge
- Diagnose and repair
- Loglune
MTTR is the mean time a team takes to get a failed system or service working again, averaged over a set of failures, and the R can stand for repair, recovery, resolve, or respond. This guide measures and reduces MTTR in 7 steps: choose which MTTR the team means, record the timestamps that start and stop the clock, calculate the mean, split the time into stages, report deployment failures separately, find the change that reached the affected customer, and restore service with a rollback that needs no deploy.
The steps apply to software services run by a team with an incident management process. They close a common gap: a monthly MTTR number that changes meaning from report to report because nobody wrote down which MTTR it is or when the clock starts. After reading, the team can fix one definition, calculate it the same way every month, and see which stage of an incident takes the most time. MTTR for physical equipment uses the same arithmetic and is outside the scope.
What MTTR means
Atlassian’s page Common Incident Management Metrics says MTTR can represent four different measurements, because the R can stand for repair, recovery, respond, or resolve, and advises a team to agree on which MTTR it means before tracking it. The four variants start and stop the clock at different points.
| MTTR variant | Clock starts | Clock stops | What it shows |
|---|---|---|---|
| Mean time to repair | Repair work begins | The system is fully functional again, testing included | How fast the repair work goes |
| Mean time to recovery, or to restore | The system fails | The system is fully operational again | The speed of the whole recovery process |
| Mean time to resolve | The system fails | Work to keep the failure from recurring is done | Recovery plus prevention |
| Mean time to respond | The first alert | The system is fully functional again | Recovery time without the lag before the alert |
Related metrics have their own formulas.
| Metric | Formula |
|---|---|
| MTTR, mean time to recovery | Total downtime ÷ number of incidents |
| MTTA, mean time to acknowledge | Total time from alert to acknowledgment ÷ number of incidents |
| MTBF, mean time between failures | Total operational time ÷ number of failures |
| Availability | MTBF ÷ (MTBF + MTTR) |
MTBF and MTTR measure opposite sides of a failure: MTBF measures how long a system runs between failures, and MTTR measures how long the system takes to get working again after one. MTBF is the average time between repairable failures of a technology product. A server that runs 24 hours a day for 30 days has 720 hours of operation, so 2 failures give an MTBF of 360 hours. Higher MTBF and lower MTTR lead to better system uptime, and mean time to failure (MTTF) is used instead of MTBF for non-repairable systems.
Before you measure MTTR
Four inputs decide whether the number means the same thing from month to month.
- An incident record with the times of the failure, the alert, the acknowledgment, the restored service, and the close.
- A rule for which incidents count, such as every incident at or above a severity level.
- A clock rule: wall-clock hours or business hours.
- A cause field that separates deployments, flag or configuration changes, and external failures.
How to measure and reduce MTTR in 7 steps
1. Choose which MTTR your team means
Pick one of the four variants and write its start and stop points into the incident process. The four measurements overlap but each has its own meaning, so a team talking about tracking MTTR should first clarify which MTTR it means. For a customer-facing service, mean time to recovery covers the whole outage, from the failure to full operation.
2. Record the timestamps that start and stop the clock
Record each timestamp when it happens instead of reconstructing it after the incident: the failure start from application performance monitoring or the first customer report, the alert, the acknowledgment, the restored service, and the end of the follow-up work. Atlassian notes that mean time to resolve is most frequently calculated in business hours, and that a team with on-call staff or several locations needs to define how it tracks time for mean time to resolve.
3. Calculate MTTR with the formula
MTTR is the total time for the chosen variant divided by the number of incidents. In a simple example for mean time to recovery, 30 minutes of downtime across two incidents in 24 hours gives an MTTR of 15 minutes. For a month with four incidents that took 12, 45, 20, and 83 minutes from failure to restored service, the total is 160 minutes and the mean time to recovery is 160 ÷ 4 = 40 minutes. The monthly numbers are illustrative.
4. Split MTTR into stages to see where the time goes
A single mean does not show whether the time went to detection, diagnosis, or repair. Layering the variants helps: mean time to recovery shows how quickly systems come back, adding mean time to respond shows how much of the recovery time belongs to the team and how much to the alert system, and adding mean time to repair separates repair time from diagnosis time. MTTA is a measure of the team’s responsiveness that can expose alert fatigue.
Record three stage durations per incident: failure to alert, alert to acknowledgment, and acknowledgment to restored service. The stage with the largest share is the first place to shorten.
5. Report failures caused by deployments separately
DORA’s post A history of DORA’s software delivery metrics (January 2, 2026) says DORA renamed and redefined mean time to recover, or time to restore service, as failed deployment recovery time in 2023, so MTTR is no longer one of the DORA metrics under that name. Since 2024, DORA uses five metrics: change lead time, deployment frequency, failed deployment recovery time, change fail rate, and deployment rework rate. The reason given for the rename is that the earlier definitions did not distinguish a failure initiated by a software change from a failure caused by external factors, such as a data center outage. DORA’s guide to its software delivery performance metrics (last updated January 5, 2026) defines failed deployment recovery time as the time it takes to recover from a deployment that fails and requires immediate intervention.
Tag each incident with its cause, then report mean time to recovery for all incidents and failed deployment recovery time for the incidents a deployment caused. Decide whether flag and configuration changes count with deployments and write the rule down, because DORA’s definition names deployments. DORA’s guide also says the DORA metrics suit one application or service at a time, and cautions that setting the numbers of very different applications side by side, a mobile app next to a mainframe system for instance, gives a misleading picture.
6. Find which change reached the affected customer
In an incident caused by a change, part of the time between acknowledgment and restored service goes to working out which changes were live for the affected customer when the failure started: the build, the configuration, and the flag rules. Build versions come from the deploy log. Flag rules can change several times a day without a deploy, so the flag state at the failure time needs its own record.
In Loglune, every flag edit is appended to the change history as a change event with the customer, the actor, the time, the target flag, and the values before and after. Pick the affected customer and the time the failure started, and Loglune rebuilds the flag state at that time from the change history and delivers it in reproduction mode to a development, CI, or staging environment. One delivery counts as one reproduction, and Loglune reproduces the flag evaluation, not the root cause in application code. The walkthrough on reproducing a bug that affects one customer shows the path from a customer report to a reproduction.
Loglune’s example dataset shows the diagnosis stage for one flag-related failure. The dataset is synthetic input labeled Example data in the Loglune console at loglune.com/app, visible without signing in, and it describes no customer and no real incident. The example bug-report fingerprint ex-fp-2, recorded on August 23, 2026, at 07:48 UTC, carries version 3 of the flag configuration and the value checkout-v2 = on with the reason default. The console’s Bisect a regression panel searches the flag change history the way git bisect searches commits. Run for a customer on the free plan with checkout-v2 = on judged as bad, the panel names one culprit: the edit that jordan@example.com made on August 20, 2026, at 11:15 UTC, which switched the default variation of checkout-v2 from off to on and published version 3. The same free-plan customer bisected at August 18, 2026, at 13:22 UTC gets the verdict none, because checkout-v2 still returned off at that time, and the example fingerprint ex-fp-1 recorded at that time carries version 2 and checkout-v2 = off. The example reproduction history for August 2026 counts 3 reproductions, two of version 3 and one of version 2.
7. Restore service with a rollback that needs no deploy
The Google SRE book chapter Managing Incidents lists the priorities of an incident as stopping the bleeding, restoring service, and preserving the evidence for root-causing. A feature flag that switches the new code path off restores service without a build and a deploy. Pete Hodgson’s article Feature Toggles (October 9, 2017) says ops toggles have to be re-configured extremely quickly when operations staff react to production issues, and that rolling out a new release to flip one is unlikely to satisfy them.
In Loglune, the edit that switches a flag off is itself a change event with the actor and the time, so the rollback keeps the evidence the incident review needs.
Editorial example (not a customer case): one month of incidents and where the time went
The table splits four incidents into stages. Times and causes are illustrative.
| Incident | Failure to alert | Alert to acknowledgment | Acknowledgment to restored | Failure to restored |
|---|---|---|---|---|
| 1, database failover | 0 min | 3 min | 9 min | 12 min |
| 2, flag rule edit put one customer on a new pricing path | 10 min | 5 min | 30 min | 45 min |
| 3, deployment with a slow query | 2 min | 4 min | 14 min | 20 min |
| 4, third-party API outage | 5 min | 8 min | 70 min | 83 min |
The mean time to recovery for the month is (12 + 45 + 20 + 83) ÷ 4 = 40 minutes. The failed deployment recovery time covers incident 3 alone, at 20 minutes. Incident 2 spent 30 of its 45 minutes between acknowledgment and restored service, and in the example most of that went to finding that a flag rule edit had put the reporting customer on the new pricing path. Rebuilding that customer’s flag state at the failure time shows the value the customer received, and switching the rule back restores service without a deploy.
Troubleshooting MTTR
- MTTR looks low while customers report long outages: check whether the clock starts at the alert, because mean time to respond leaves out the lag before the alert.
- Two teams report different MTTR for the same incidents: agree on the variant and the clock rule, business hours or wall-clock hours.
- One long incident swings the monthly mean: publish the incident list with the stage split next to the mean, because DORA warns against measuring a complex system with one metric.
- MTTR jumps after a change in which incidents count: keep the severity rule fixed, and compare periods under the same rule.
- Incidents close early to improve the number: stop setting MTTR as a target, because DORA warns that setting metrics as goals makes teams more likely to game them.
- Diagnosis takes most of the time in change-caused incidents: record every flag and configuration change with its time and actor, and rebuild the affected customer’s flag state at the failure time.
FAQ
What is a good MTTR?
No single target fits every service. DORA’s guide says context matters and that the DORA metrics suit one application or service at a time, and MTTR also depends on the severity of failures. Compare a service’s MTTR with its own earlier periods under the same counting rule.
Deciding which MTTR to report
Report mean time to recovery for a customer-facing service with the stage split beside it, and report failed deployment recovery time for the incidents a deployment caused. Keep the counting rule fixed across periods and compare a service with its own history. Record every flag change with its time, so the diagnosis stage of a change-caused incident starts from the flag state the affected customer had when the failure began.
See the flag state an affected customer had, a step that counts toward MTTR
In a change-caused incident, part of the recovery time goes to working out which change reached the affected customer. Loglune records every flag edit as a change event with the actor, the time, and the values before and after, and rebuilds the flag state a customer had at time T for your development, CI, or staging environment. The Free plan includes 5 reproductions.